
AI Experiments
Local LLM experiments, benchmarks on DGX Spark and RTX hardware, and practical AI/MLOps workflows from the DevFortunato lab.
Why I'm Betting on Local AI (and How You Can Start)
LLMLocal AIDGX Spark
OpenAI just halved its $200 plan and closed models keep adding guardrails. Why I'm betting on local AI, and how to start with quantization, inference engines, recipes and harnesses.
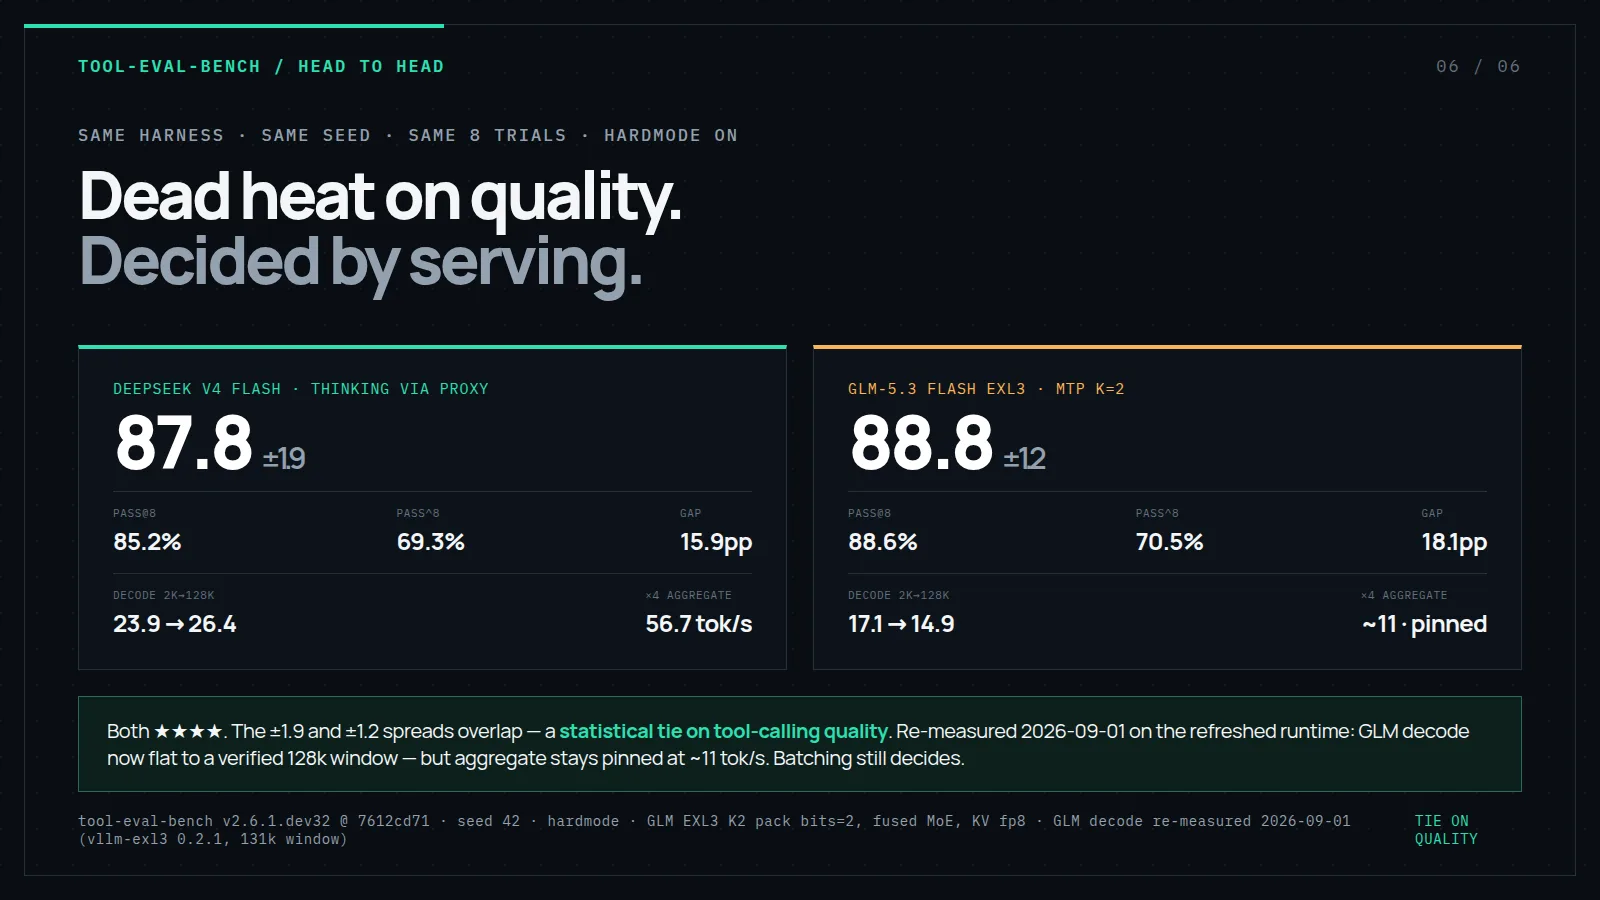
DeepSeek V4 Flash vs GLM 5.3 Flash: Who Wins on a Single Spark?
LLMDeepSeek V4 FlashGLM-5.3
DeepSeek V4 Flash faces GLM-5.3 Flash EXL3 on one DGX Spark across tool calling, serving, and 128k-context decode benchmarks, with full measured results.
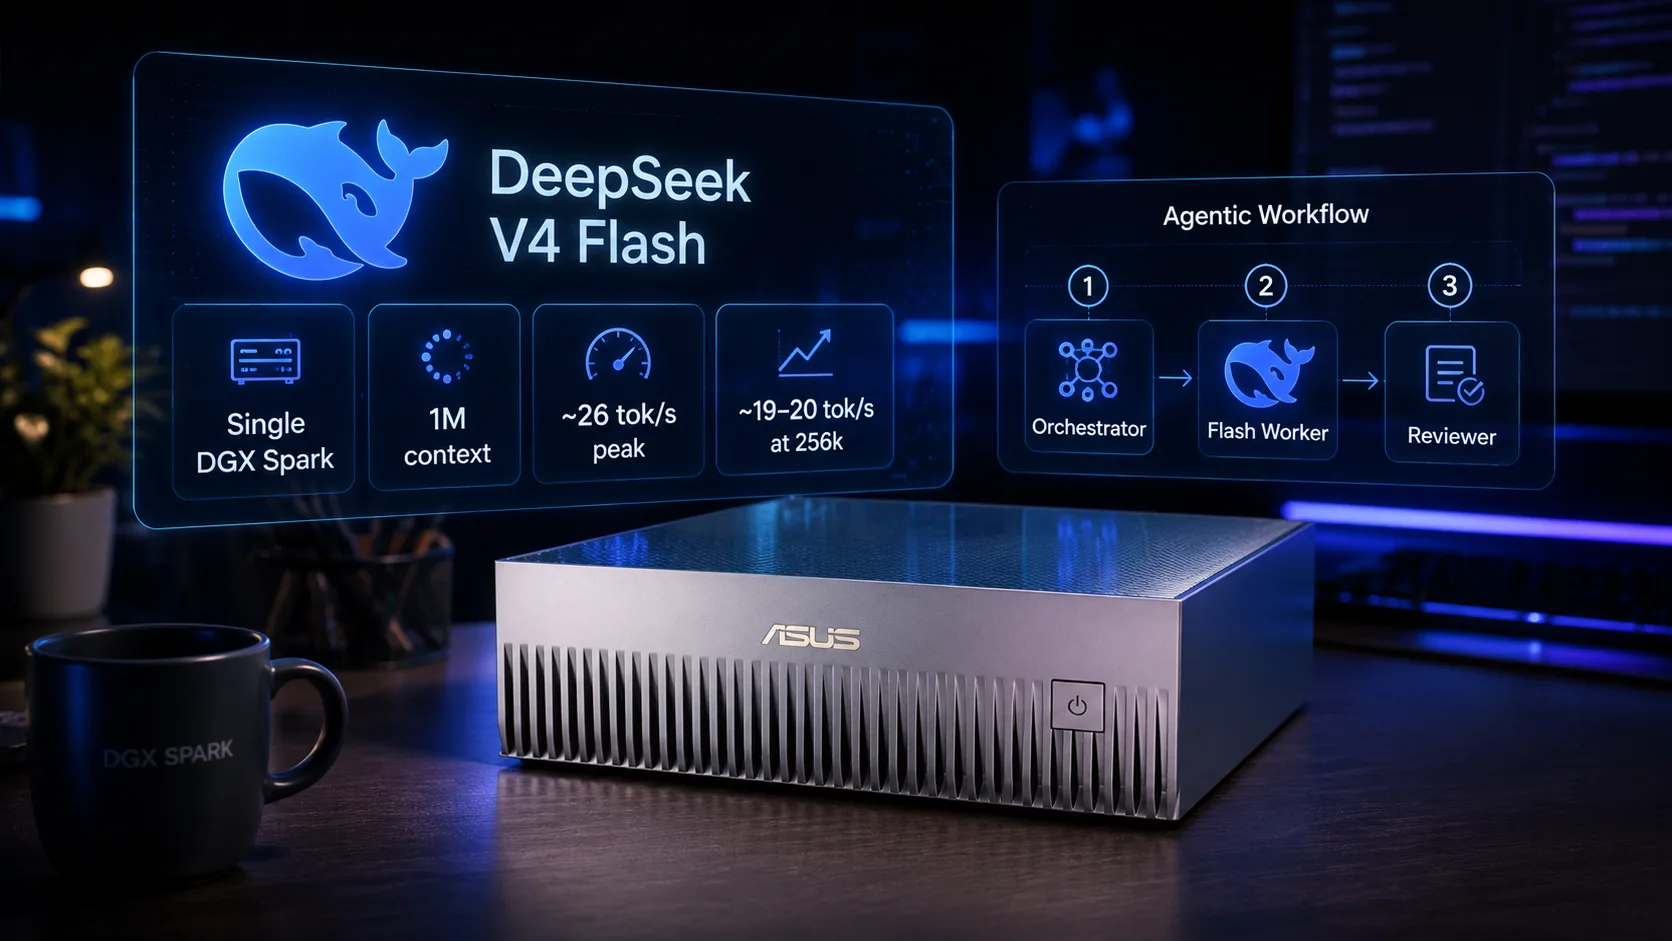
DeepSeek V4 Flash on a Single DGX Spark
LLMDeepSeek V4 FlashDGX Spark
I ran DeepSeek V4 Flash on one DGX Spark with the MiaAI-Lab recipe, benchmarked throughput to 256k context, compared a GGUF path, and wired it into a Hermes kanban agent pipeline.
Running Laguna S 2.1 on a DGX Spark
LLMLaguna S 2.1DGX Spark
How I fit and serve Poolside Laguna S 2.1 on a single NVIDIA DGX Spark using NVFP4, vLLM, DFlash speculative decoding, and a hardened thinking-off configuration.
My Obsidian PKM Setup: Karpathy's LLM Wiki + Claude Code + Local Search
obsidianpkmknowledge-management
My Obsidian PKM setup using Karpathy's LLM wiki pattern: Claude Code maintains the wiki, and qmd handles local search without the usual RAG overhead.
Gemma 4 E4B vs 26B on an RTX 4070 Ti: Benchmarks, RAG, and a Real Webapp Test
LLMGemma 4llama.cpp
I benchmarked Gemma 4 E4B and Gemma 4 26B locally with llama.cpp on an RTX 4070 Ti to see which one is better for local RAG, web retrieval, and grounded summaries.