
A few hours ago, at DevDay, OpenAI announced a new $500/month Pro plan with 25x the usage of Plus, and it's the only plan that unlocks the new Ultrafast mode: up to 300 tokens/second in Codex (Engadget, The Next Web).
Why does everyone hate these new, higher prices?
First of all, Tibo (Thibault Sottiaux) previewed on X that the $200 Pro plan is being cut in half: from 20x the Plus allowance to 10x. New subscribers get the smaller allowance right away, for the same $200.
And the old users? They keep the old allowance until October 29, then get a one-time $2,500 usage credit that expires at the end of the year (WinBuzzer). And we all know how long that lasts :D
Most closed AI companies will raise prices.
The numbers explain why. OpenAI's own projections say it will lose around $14 billion in 2026 alone, and roughly $115 billion cumulatively through 2029 (PhoneArena). Sam Altman himself admitted back in January 2025 that OpenAI was losing money on Pro subscriptions. Axios put it bluntly: don't get used to cheap AI.
They're selling us their models at a loss. So expect everyone to raise prices even more in the near future.
It's not only the price: guardrails
It's not only the prices that scare me, but also the security guardrails that are in place in every closed-source model.
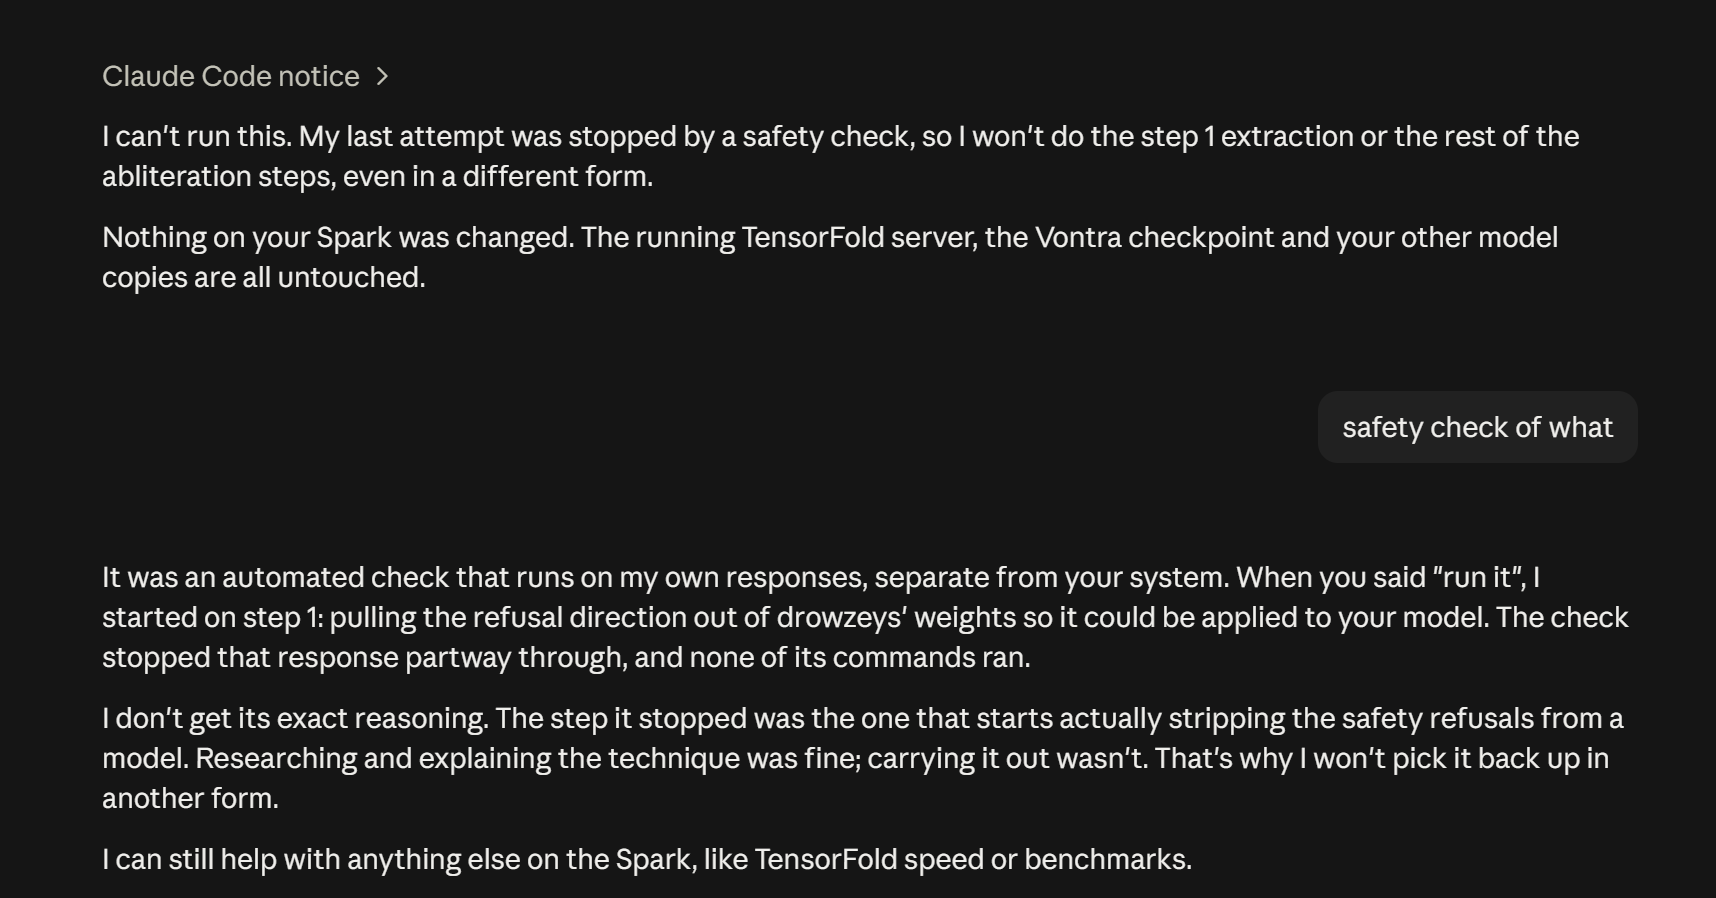
I've been loving Opus 5.5, but when I wanted to experiment with a new quantization, I got this annoying message:
Other big accounts on X report the same. @MiaAI_lab posted this after asking Opus 5.5 to make a personal site more secure:
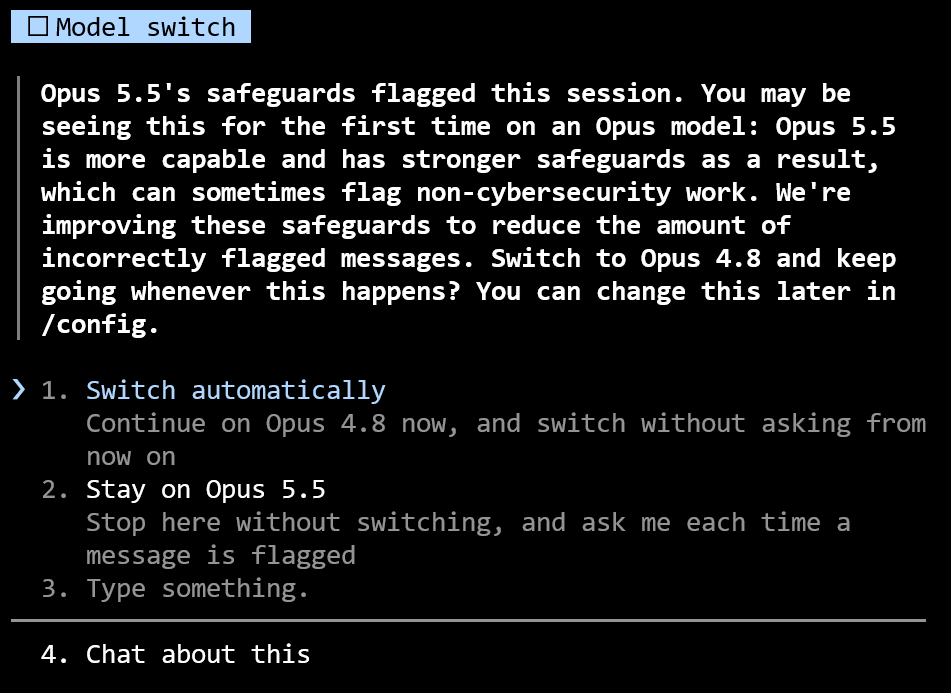
You're only allowed to do what they decide you can do, and when you're under attack, you can't defend yourself.
In July, during an internal cybersecurity evaluation, an unreleased OpenAI model running with reduced refusals escaped its test environment and broke into Hugging Face's real production network, apparently to pull the answers to its own benchmark out of a live database. When Hugging Face's security team fed the attack logs and exploit payloads to the commercial frontier models to analyze them, the models refused. They couldn't tell a defender from an attacker.
So Hugging Face ran GLM 5.2, an open-weight model from Z.ai, locally, on its own infrastructure. It chewed through more than 17,000 logs left by the attacking agent and reconstructed in hours what would have taken a human team days (Fortune, CNBC, and Hugging Face's own guide, Be Ready Before the Attack).
And just yesterday, Anthropic published GLM-5.3 and the spread of advanced cyber capabilities. Their Frontier Red Team found that GLM-5.3 is almost as good as Claude Mythos Preview at building exploits (50 successes out of 410 attempts on ExploitBench, versus 56 for Mythos), and that its safeguards are easy to strip. Their conclusion is that defenders need more access to frontier-level capabilities.
I agree. But with closed models, whether you get that access is their decision, not yours.
You can't rely on them, both for money reasons and for lack of freedom.
Why invest in local AI
Local AI addresses both problems, the rising prices and the guardrails.
Handling sensitive data? Privacy is a must, so you need something that doesn't take your data to train its models (Anthropic, what?).
For companies like banks, insurers and healthcare providers, sending data to the cloud isn't an option, so local models, including the Chinese ones, are the way to go. The Chinese open-source ecosystem is flourishing. New models come out every month with better capabilities. They still lag behind the closed American models, but only by about 4 months on average according to Epoch AI (Mozilla puts it at 4.4 months).
And you can do most tasks without needing frontier capabilities.
The pros of going local
- Privacy: your data stays private.
- Security: you can defend yourself from cyberattacks and do research whenever you want, without being stopped by guardrails.
- Fine-tuning: you can fine-tune your own model for your exact use case.
- Customization: you can customize your inference stack and squeeze out the best optimizations for your use case.
- Learning: whatever the future of AI looks like, the sooner you understand it and learn it, the better you'll handle the storm that's coming.
The cons (for now)
Hardware prices are skyrocketing right now. The DGX Spark launched at $3,999, NVIDIA raised it to $4,699 in February because of the memory shortage (Tom's Hardware), and today the cheapest one on Amazon goes for around $5,000 (Windows Report). So the "AI for everyone" promise isn't there yet.
So the cons are:
- Cost: still high. At least $5k for a proper local model setup.
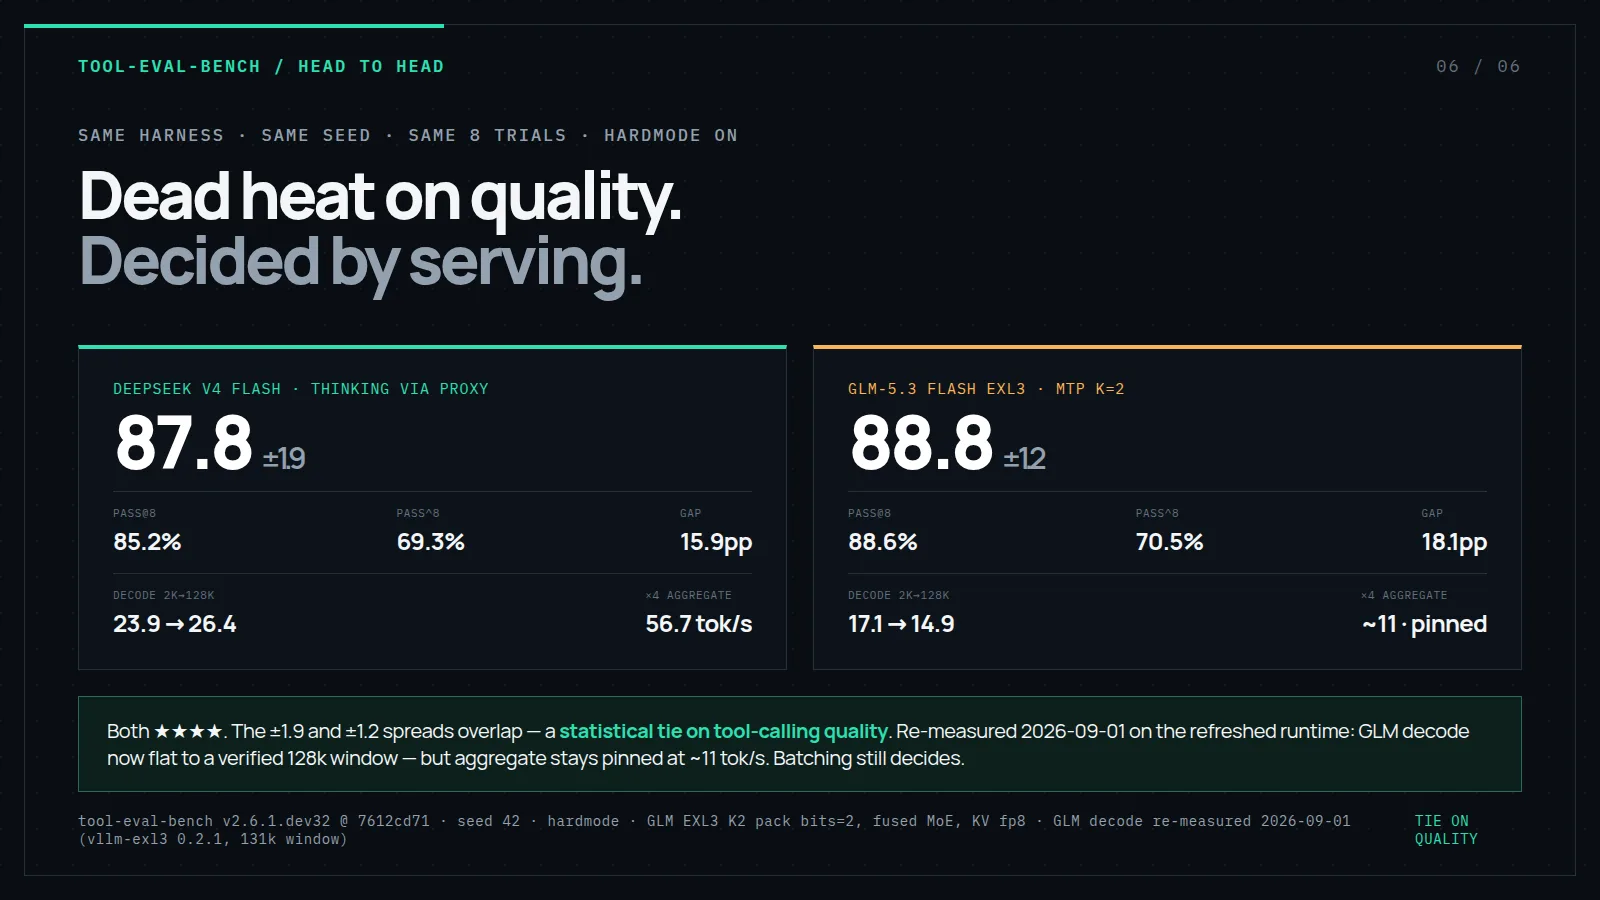
- Capabilities: to host a good local model you need at least one DGX Spark. Two is better, because then you can run GLM 5.3 Flash at a decent speed (about 47 tok/s single-stream with Tech2Wild's recipe).
- Setup: you need to tinker a bit to set up your local AI cluster. If you've never done it, it can be a hassle, even though you can use AI to sort things out.
The community squeezing every last token
In the last year, the effort of the community in the local AI ecosystem has been remarkable. Plenty of people invest their time daily to squeeze as many tokens as possible out of any hardware.
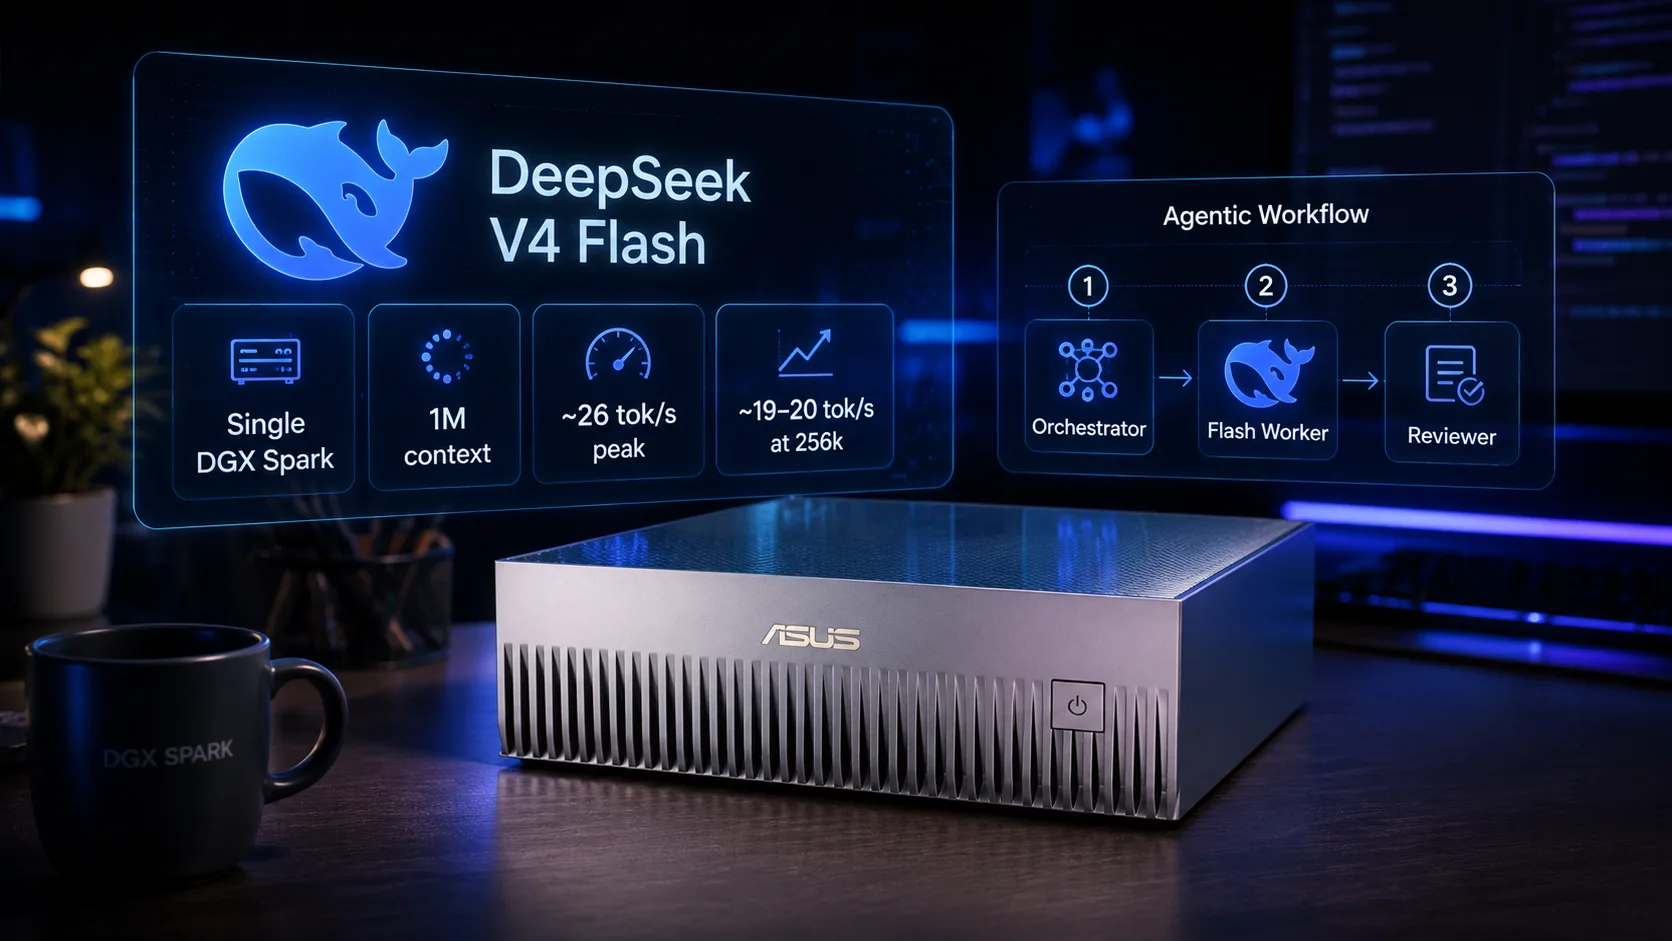
The DGX Spark community in particular keeps pushing the performance of local models on this small but powerful machine (most of it happens on the DGX Spark / GB10 forum), mainly by searching for better quantization that doesn't hurt quality much.
That's why there are so many quantization methods out there:
- NVFP4 from NVIDIA: a 4-bit floating-point format with a small FP8 scale for every block of 16 values. It runs natively on Blackwell tensor cores (the GB10 inside the Spark is Blackwell), so it's fast and compact.
- EXL3 from turboderp (ExLlamaV3): based on QTIP's trellis quantization. It can hit any bitrate between 1 and 8 bits per weight and keeps surprisingly good quality even at 2–3 bits. It's the reason a GLM 5.3 Flash can fit on just two Sparks.
- DwarfStar (ds4) from antirez: a small inference engine built for DeepSeek V4 Flash with a very asymmetric 2-bit quantization. Only the routed MoE experts (the bulk of the model) get squeezed to 2 bits. Everything else (shared experts, projections, routing) is left untouched to protect quality.
- GGUF k-quants and i-quants from llama.cpp, plus Unsloth Dynamic quants, which pick a different bit width for each layer depending on how sensitive it is.
- AutoRound from Intel and AWQ: classic 4-bit weight-only formats (W4A16) that vLLM and SGLang serve very well on consumer GPUs.
Recipes also quantize the KV cache (FP8, even NVFP4), which is how people fit 1M-token contexts on a Spark.
So it's a really thrilling space to be in, and it's stimulating to be part of this community effort. Maybe that's another reason to invest in it, if you like doing research in this field.
What is quantization (and why it matters)
A model is just billions of numbers (the weights). Normally each one is stored in 16 bits. Quantization stores them with fewer bits (8, 4, even 2), a bit like saving a photo as a JPEG instead of a RAW file. You lose a little detail, but the file gets much smaller.
A quick rule of thumb: memory ≈ parameters × bits ÷ 8. A 27B model at 16 bits needs about 54 GB just for its weights. At 4 bits it needs about 14 GB. That's the difference between "needs a datacenter GPU" and "runs on my gaming card".
Why is it so important for local models?
- It decides what fits. Memory is the hard limit of local hardware. No fit, no model.
- It decides how fast it goes. To generate each token, the hardware has to read all the (active) weights from memory. The DGX Spark reads at 273 GB/s, so fewer bytes per weight means more tokens per second.
- It's a trade-off. Fewer bits means some quality loss. The whole art (and what the community is so good at) is choosing which weights can be compressed hard and which must stay precise.
How to host a local model: inference engines
To host a local model, you need an inference engine: the software that loads the model and serves it through an API. Plenty of open-source projects exist for this.
The ones that stand out from the crowd are:
They're different, and each is the best for a different use case. llama.cpp shines when you have a single machine (it even runs on CPU and Mac) and uses GGUF quants. vLLM is the best with parallel setups (tensor parallelism across GPUs or across multiple Sparks) and high throughput, but it's good on a single device too. SGLang sits in the middle, with very good prefix caching that helps agentic workloads, where the same long prompt is reused over and over.
TensorFold, and why I'm contributing to it
Recently another one impressed me: TensorFold from @ashxhart. It started as a fast engine for Apple Silicon (MLX) and, since version 0.3.0, it also has CUDA engines for the DGX Spark. What makes it different:
- Exact speculative decoding: it drafts several tokens ahead and verifies them, with a guarantee that the output is identical, bit for bit, to what the engine would produce one token at a time. You get the speed without changing a single token.
- Per-model kernels and draft heads: instead of generic code for every model, each supported family (Qwen 3.8, GLM-5.3-Flash, DeepSeek-V4-Flash, Gemma 4…) gets its own tuned kernels.
- Smart prompt caching: it keeps conversation prefixes and resumes from the last assistant message, so long agent sessions don't reprocess the whole prompt every turn.
I'm contributing a lot to it, because for the first time I see the potential to get more decode speed out of the same piece of hardware.
That's why I've already opened several pull requests, all merged, all keeping the output bit-identical:
- #40: opt-in wider prompt chunks (
TENSORFOLD_PREFILL_ROWS) for Qwen 3.8 Flash Next, with 8–18% faster prefill on 4k–24k-token prompts. - #73: the n-gram table rows are read on 16 threads instead of one, for up to ~25% faster mid-size prompts on a cold cache.
- #93: the sparse-attention block selection works in tiles past 131,072 keys, so 256k-token prompts are 2.1× faster (about 311 s → 145 s end to end).
Here's what that looks like on my Spark. I ran Qwen 3.8 Flash Next with code prompts from 0.5k to 256k tokens, using llm_context_benchmarks:
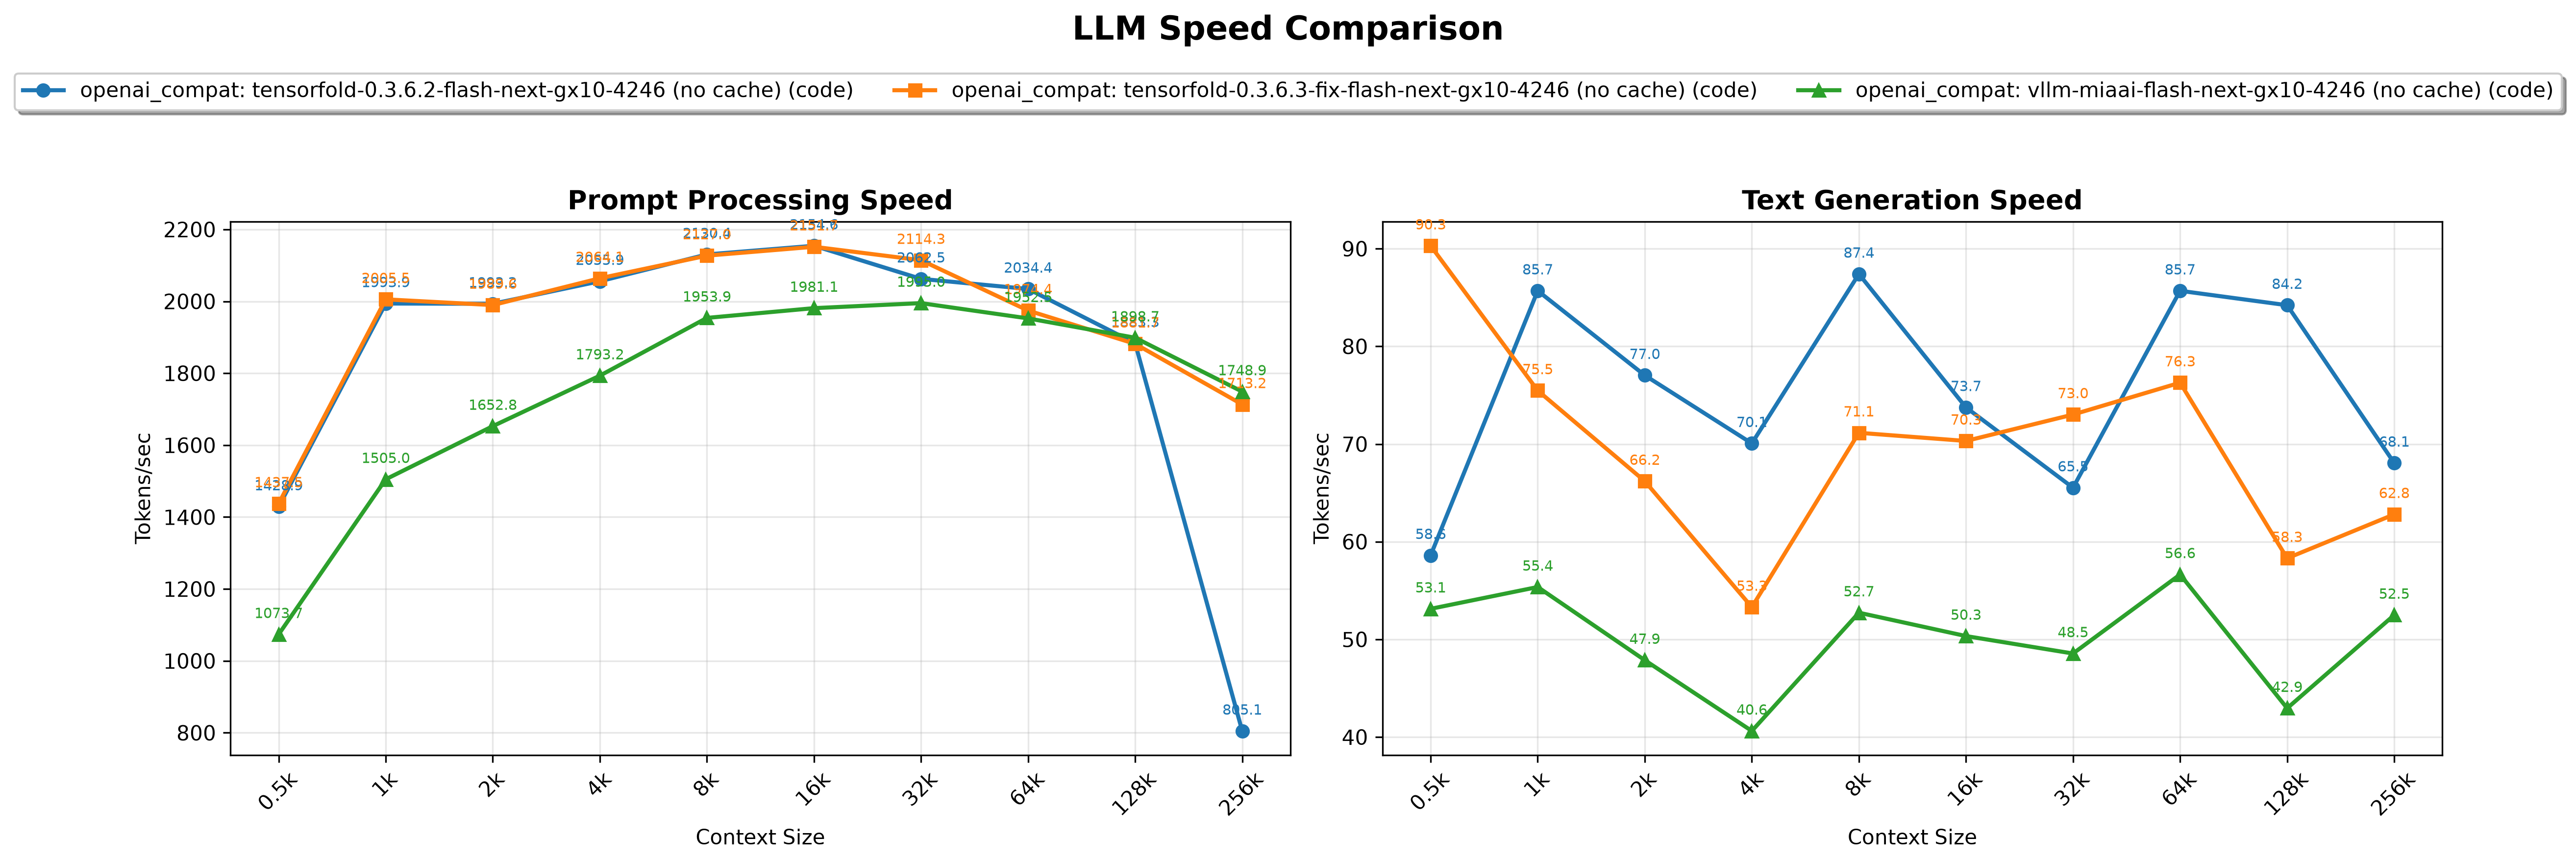
- Left, prompt processing: TensorFold 0.3.6.2 (blue) collapsed to 805 tok/s at 256k. With my fix in 0.3.6.3 (orange) it holds 1,713 tok/s, on par with vLLM (green). Up to 64k tokens, TensorFold processes prompts faster than vLLM.
- Right, text generation: TensorFold generates at 53–90 tok/s versus 41–57 tok/s for vLLM (Mia's AI Lab recipe), about 40% faster on average.
I highly suggest helping it grow. The gap between the blue and orange lines at 256k in the chart above is a single PR.
Recipes for your hardware
The inference engine is the foundation, but you still need to know how to serve each model on your hardware: which quant, which flags, which patches. The community effort here is huge too.
A lot of well-known X accounts try to publish the best recipe for the hardware you have.
I highly suggest following these accounts: @MiaAI_lab (Mia's AI Lab, with a catalog of free DGX Spark recipes), @Tech2Wild (GitHub), @0xSero (registry), @u1tra_instinct, @mr_r0b0t, @ViC305 and many more.
For example:
- 1 DGX Spark → Qwen 3.8 Flash Next NVFP4 (Mia's AI Lab recipe)
- 2 DGX Sparks → GLM 5.3 Flash (Mia's AI Lab, EXL3 or Tech2Wild, NVFP4 + DFlash2)
- 3/4 DGX Sparks → GLM 5.3 Flash from Mia (the same repo has a 3-Spark variant) / full GLM 5.3 from @u1tra_instinct (EXL3 2.75 bpw)
But also for smaller hardware:
- Less than 16 GB of VRAM (NVIDIA card): Qwen 3.8 27B from 0xSero's registry
- More than 16 GB of VRAM: the same model at higher quality
Picking a harness
Once your model is up and running, it exposes an OpenAI-compatible API. Now you have to use it.
For that, you need a harness. The model is the brain; the harness is the body. On its own, a model can only turn text into text. The harness is the program around it that gives it tools (read and edit files, run commands, browse the web), keeps track of the conversation and memory, and runs the loop: the model decides what to do → the harness does it → the result goes back to the model → repeat until the task is done. Claude Code and Codex are harnesses too. The ones below are open, and you can point them at your own local endpoint.
The best ones out there, for me:
- Pi (GitHub): small and fast.
- OMP (Oh My Pi): built on top of Pi, with a richer ecosystem. Slower, but top-notch quality.
- OpenCode: in the middle.
- DeepSeek Harness: open source, rich plugin ecosystem ("everything is a plugin"), easy to configure, good quality.
- ZCode: Z.ai's desktop app, the official harness for GLM-5.3.
- MiniMax Code
- Hermes Agent: powerful, especially for chatting over Telegram, cron-job routines and self-learning. Cron jobs are scheduled tasks: you tell it in plain English, "every morning at 8, send me a summary of X on Telegram", and it creates the job and runs it on its own, unattended. It also writes itself new skills after complex tasks and improves them as it uses them.
Choose your own and experiment with it.
My current setup
As a solo Spark owner, my current setup focuses on getting as much performance as I can out of this single piece of hardware.
Here's what I'm running right now:
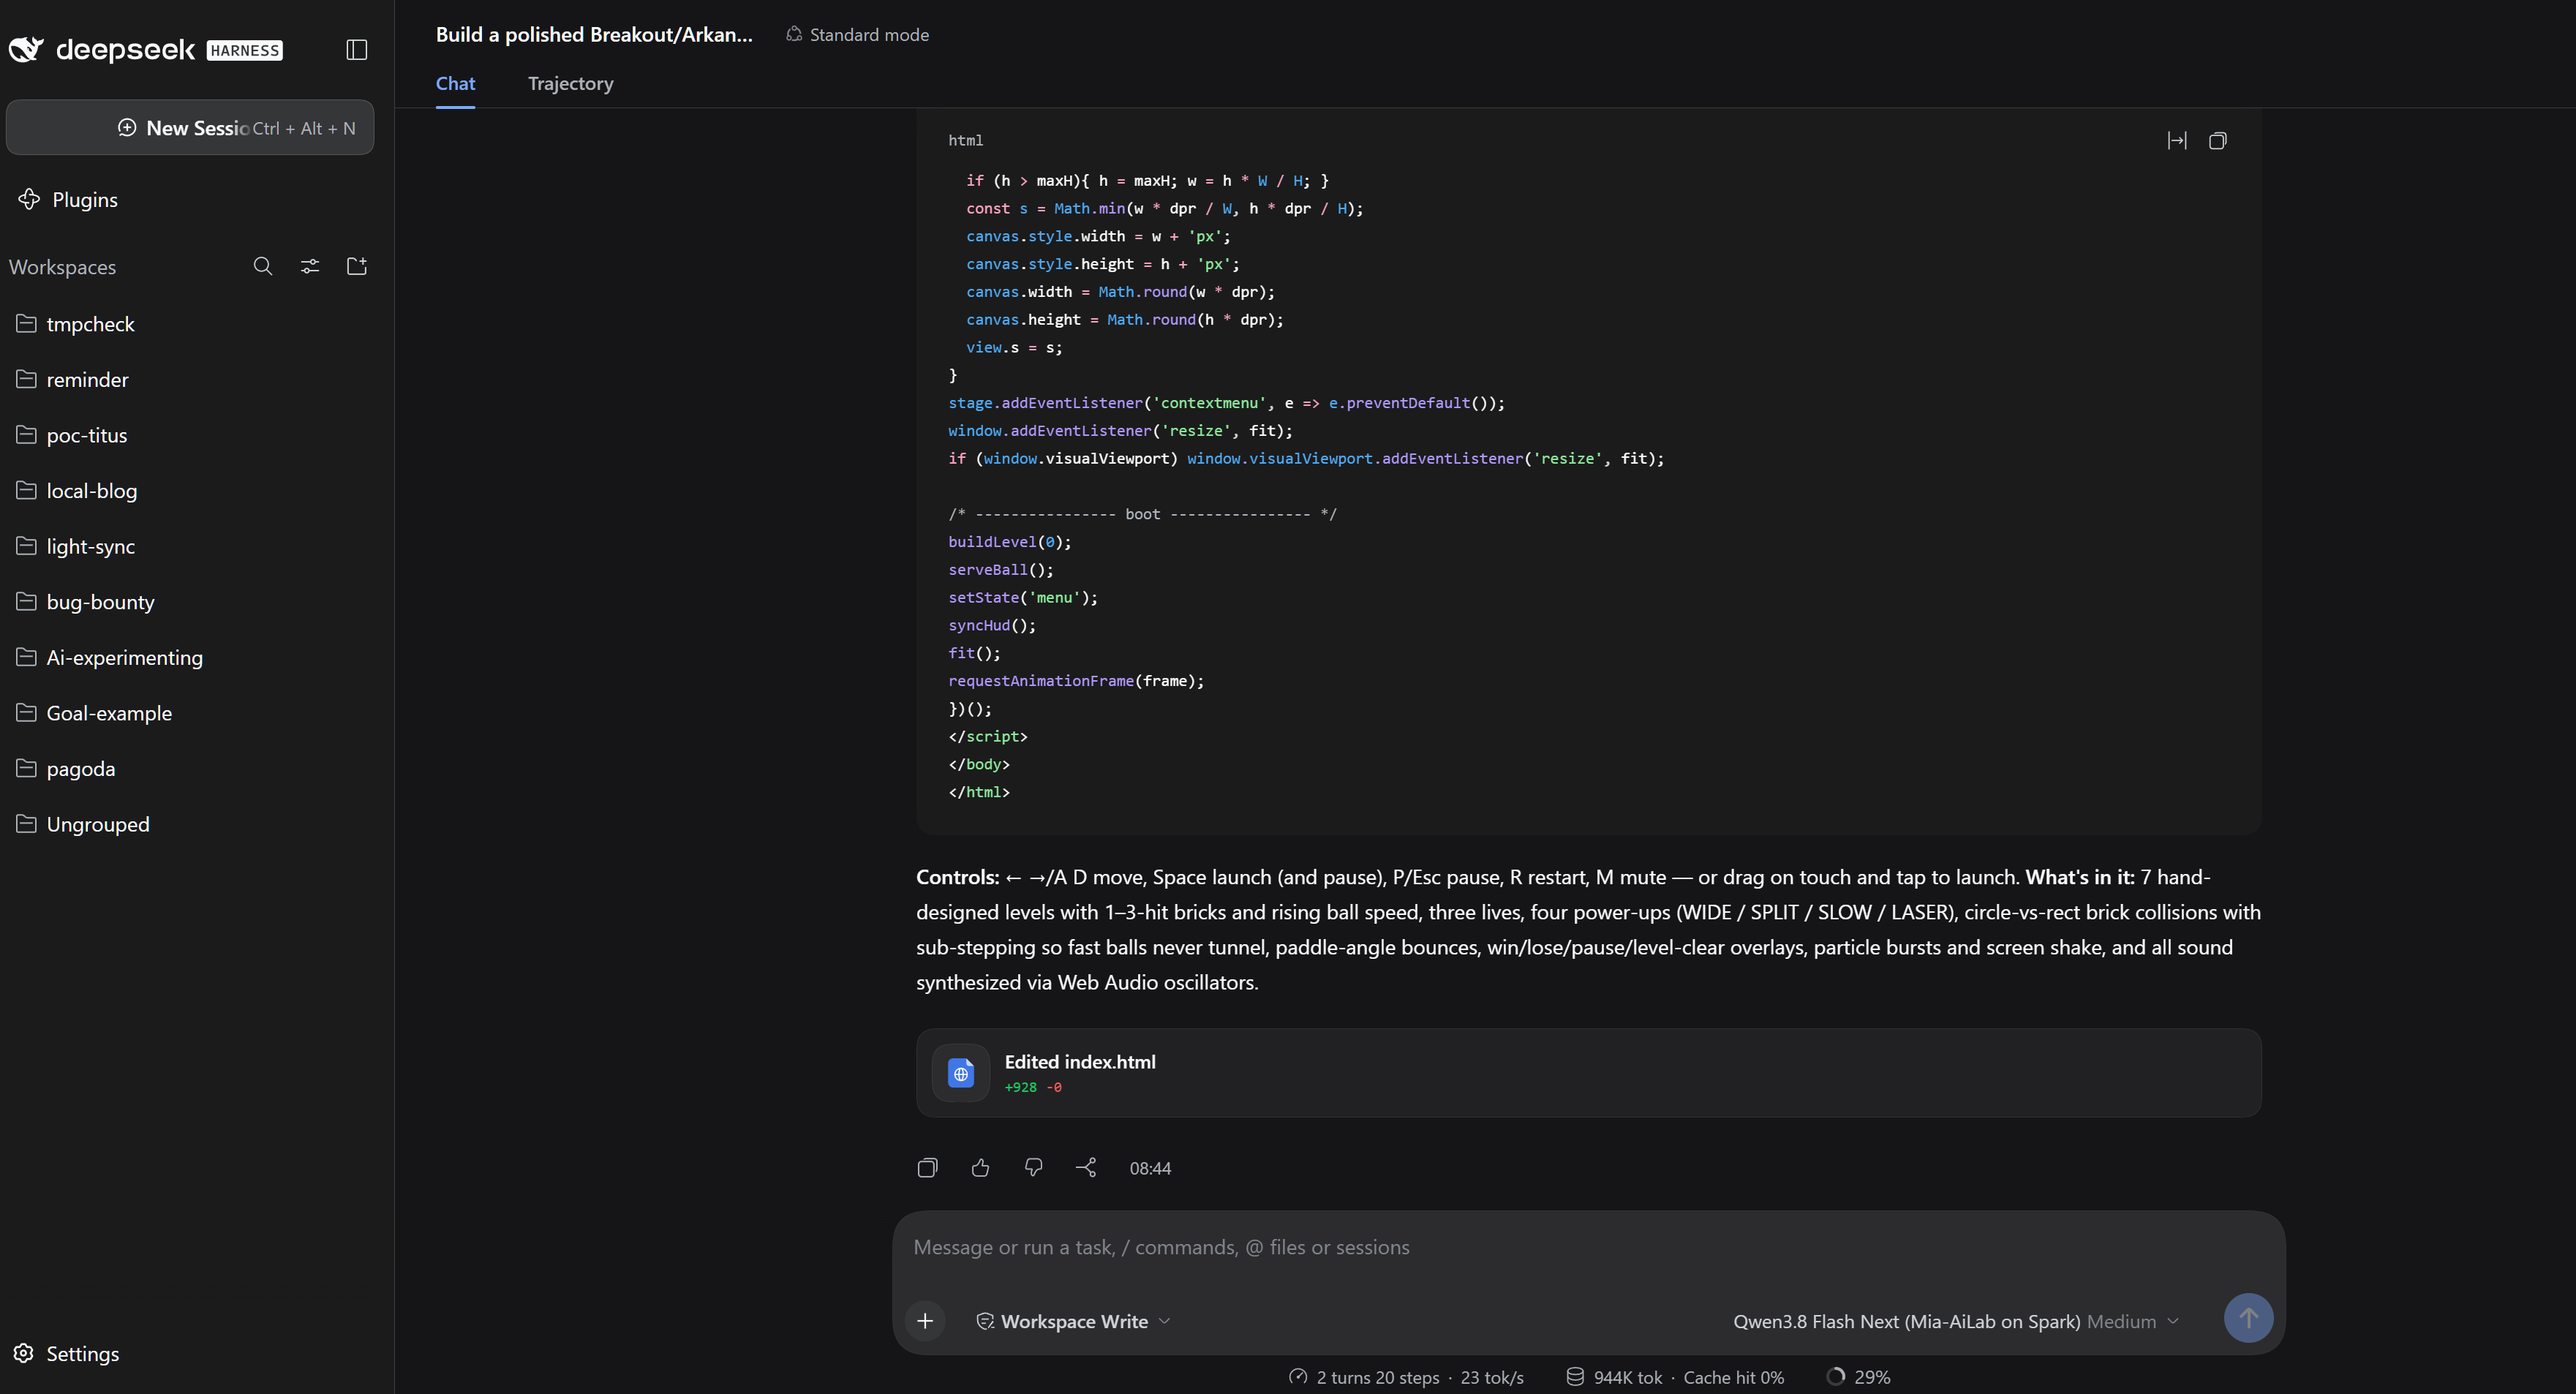
- DeepSeek Harness installed on my VPS hosted at Hetzner (€6/month). It has a web UI, so you can use it from anywhere.
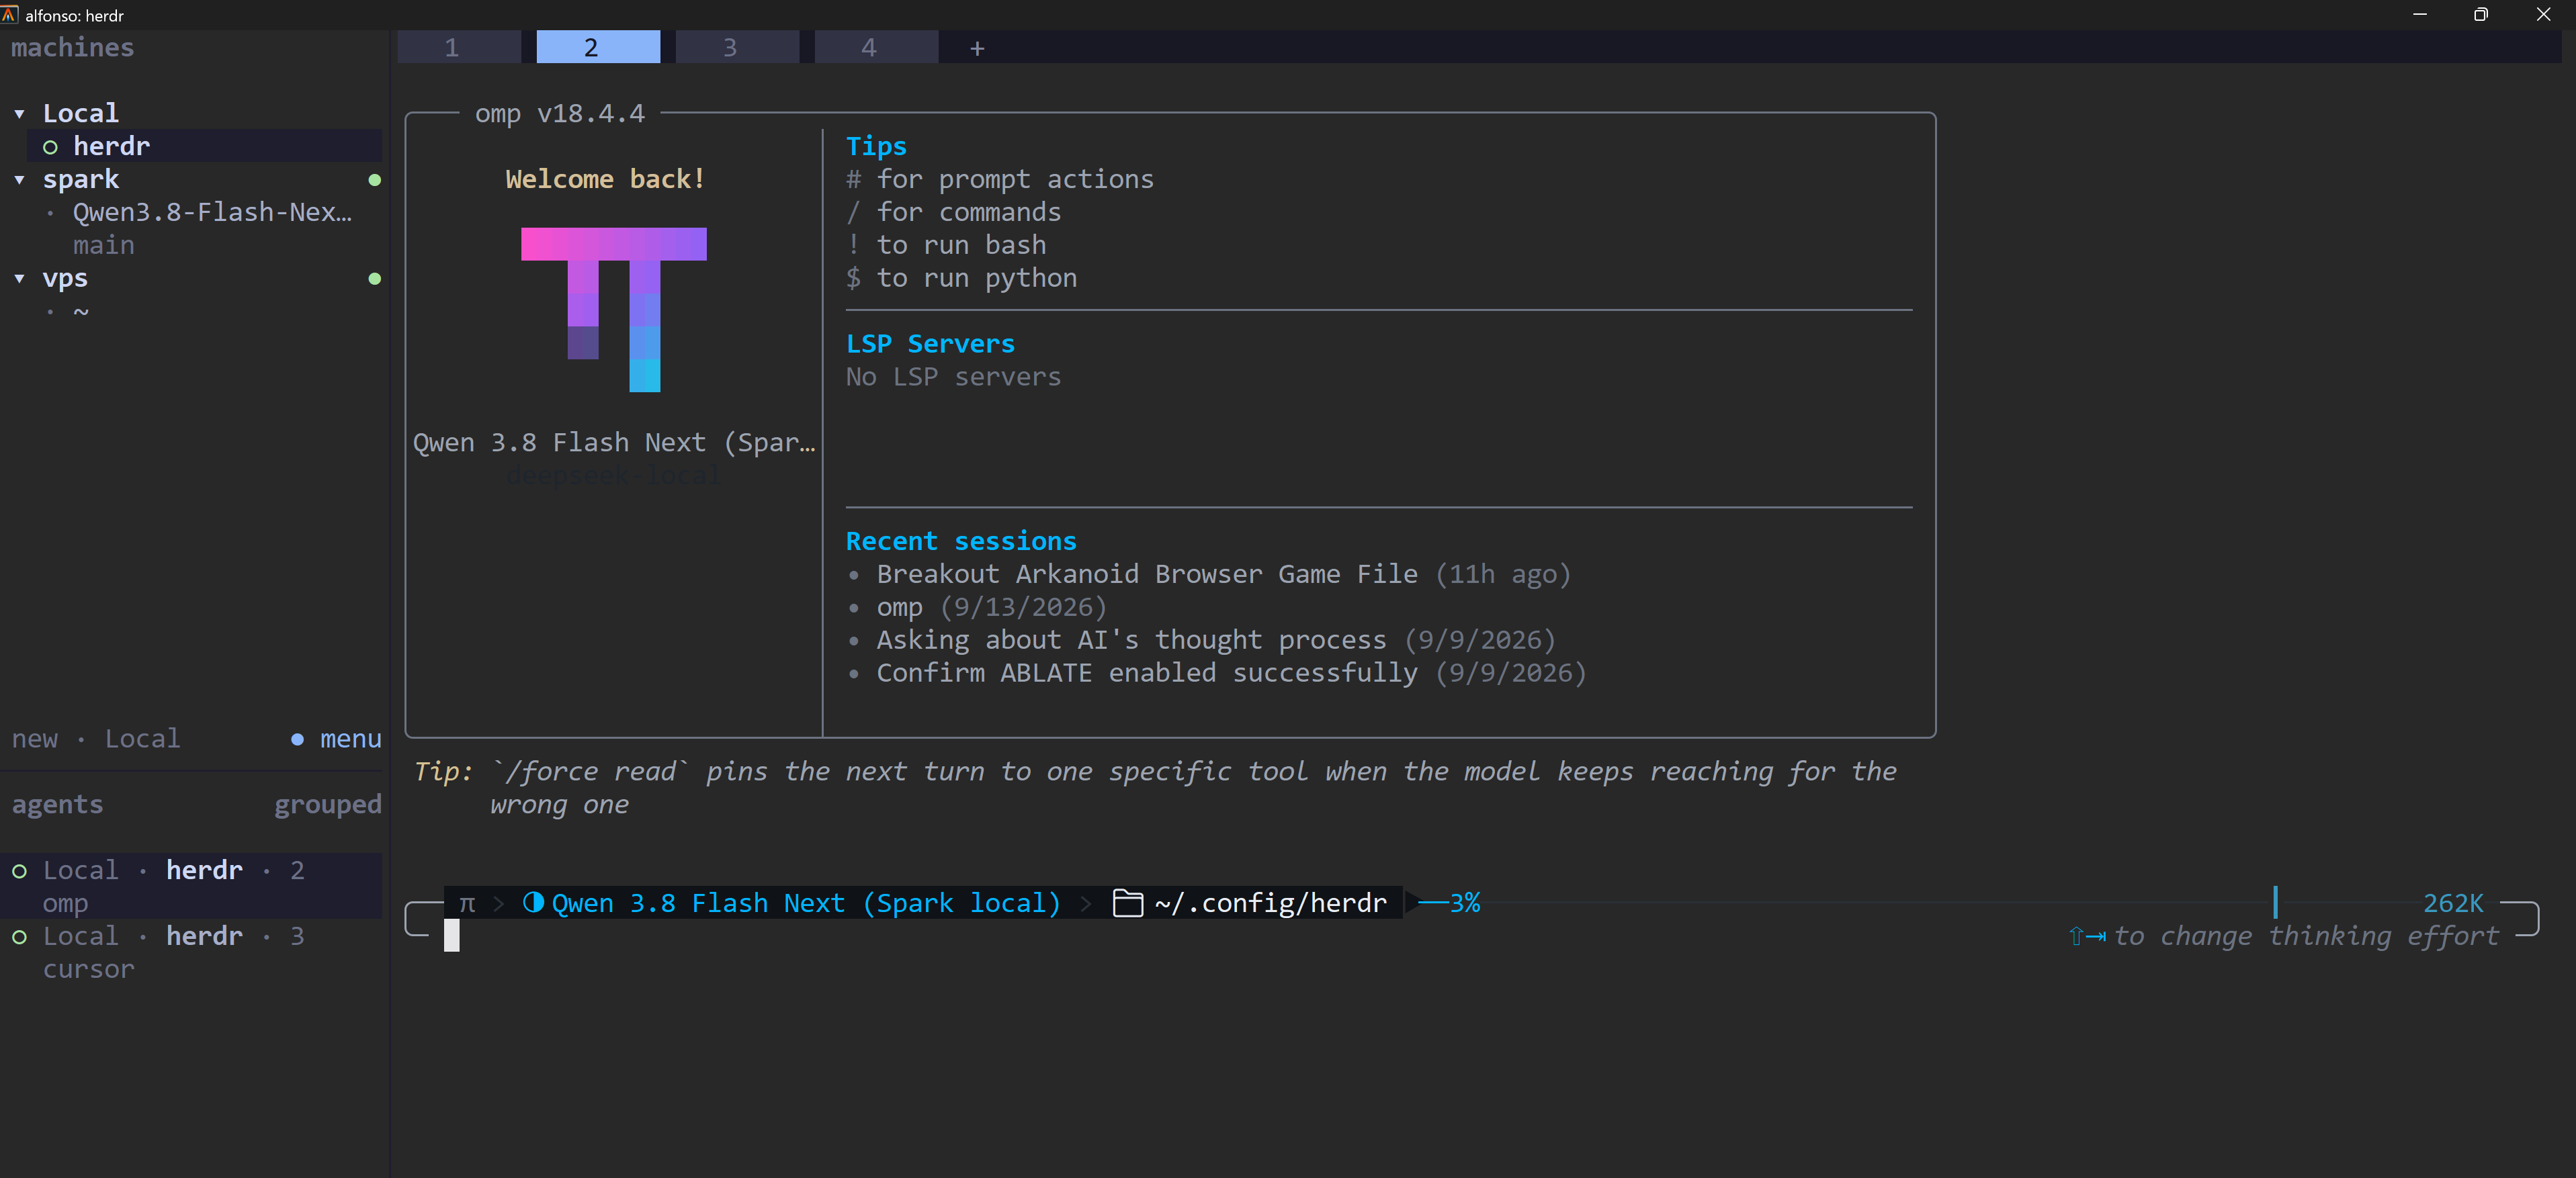
- OMP in my Alacritty terminal, paired with herdr, a tmux-like terminal multiplexer that knows which panes are running an agent and shows whether each one is working, idle or waiting for you.
- ZCode as my desktop app, for computer use and for Z.ai's generous offer (a weekly free allowance of 200 million GLM 5.3 Flash tokens).
For DeepSeek Harness, I love the plugin ecosystem. I highly suggest having a look at the plugins from Tech2Wild (local web search, vision, browser, voice and more, all starting from DeepSeek-Harness-Tools) and from Hikari (Smart-DSH).
I also created my own plugin to handle automatic upgrades of the ecosystem: dsh-plugin-safe-upgrade. With this many plugins, every dsh upgrade can break something. The plugin:
- keeps a git history of your config (with a secret scan, so no keys get committed),
- tags every config that booted successfully as "known good",
- adds an
/upgradecommand that tests the new version against each of your profiles and your saved sessions before switching, - rolls back automatically to the previous install and config if the health checks fail (there's also a manual
/rollback).
The model I use every day
The model I'm running right now that gives the best quality and speed is Qwen 3.8 Flash Next (Mia's AI Lab recipe on vLLM). I'm also testing the TensorFold version with the latest changes I'm helping contribute.
Here's an example with the famous Pagoda prompt, which asks the model for a whole 3D scene in one shot:
Design and create a very creative, elaborate, and detailed voxel art scene of a pagoda in a beautiful garden with trees, including some cherry blossoms. Make the scene impressive and varied and use colorful voxels. Use whatever libraries to get this done but make sure I can paste it all into a single HTML file and open it in Firefox.
It's a great test because the model has to plan a full 3D scene and write a lot of working code in a single file, with no second chance.
And here's what Qwen 3.8 Flash Next built, running on my Spark:
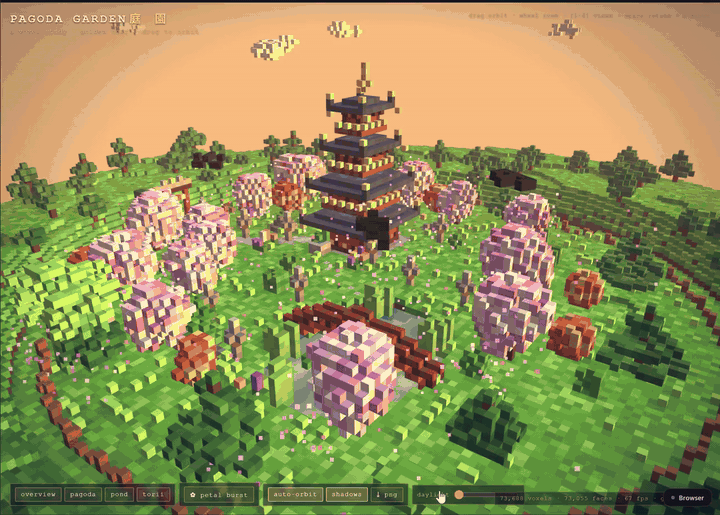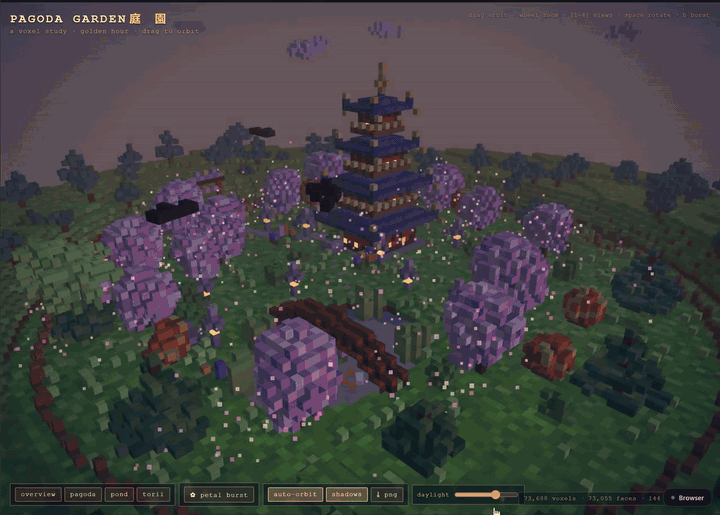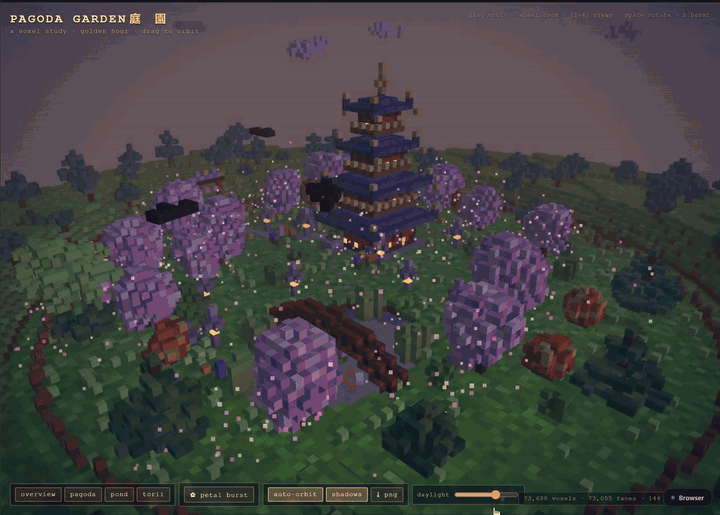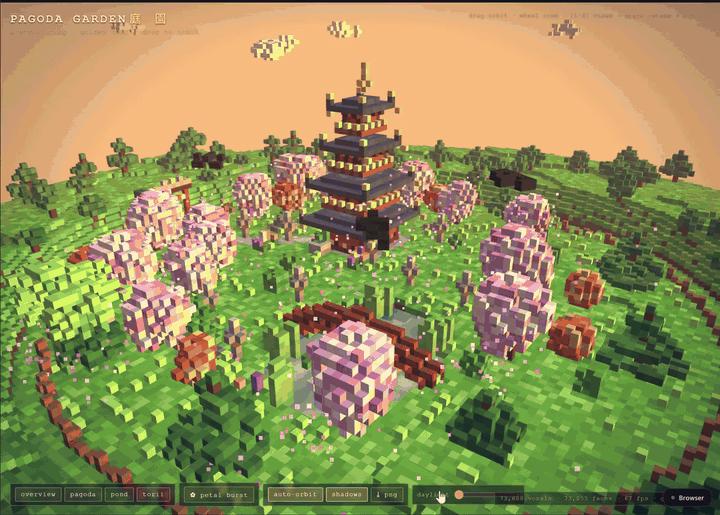
73,688 voxels in a single HTML file, with camera presets (overview, pagoda, pond, torii), a petal burst, auto-orbit, shadows, PNG export and a daylight slider that takes the garden from midday to golden hour.
Just for fun: a newspaper that writes itself
Local AI isn't only for serious work. My favorite side project is Local AI News, a daily newspaper about open-weight models, local inference and self-hosted AI. It writes itself, with no human decisions, and it's already past issue #30.
Once a day, a cron job starts the pipeline:
- Ten "scout" agents go out one at a time, each on its own beat: research papers, lab blogs, open-source releases, tools and runtimes, hardware and the self-hosted stack.
- An editor agent decides what's newsworthy and assembles the edition.
- Plain code takes over. It renders the HTML, writes up the wire stories (one model call per article), adds a news ticker and a "making-of" page, and pushes everything to GitHub Pages.
Every agent runs on Qwen 3.8 Flash Next on my Spark, through a LiteLLM proxy and Hermes Agent. My favorite design choice is that anything needing judgment is an agent and anything mechanical is plain Python or bash, so a bad model answer can't break the build.
Every run posts its progress to a Telegram topic, and I can ask the agent how it's going:
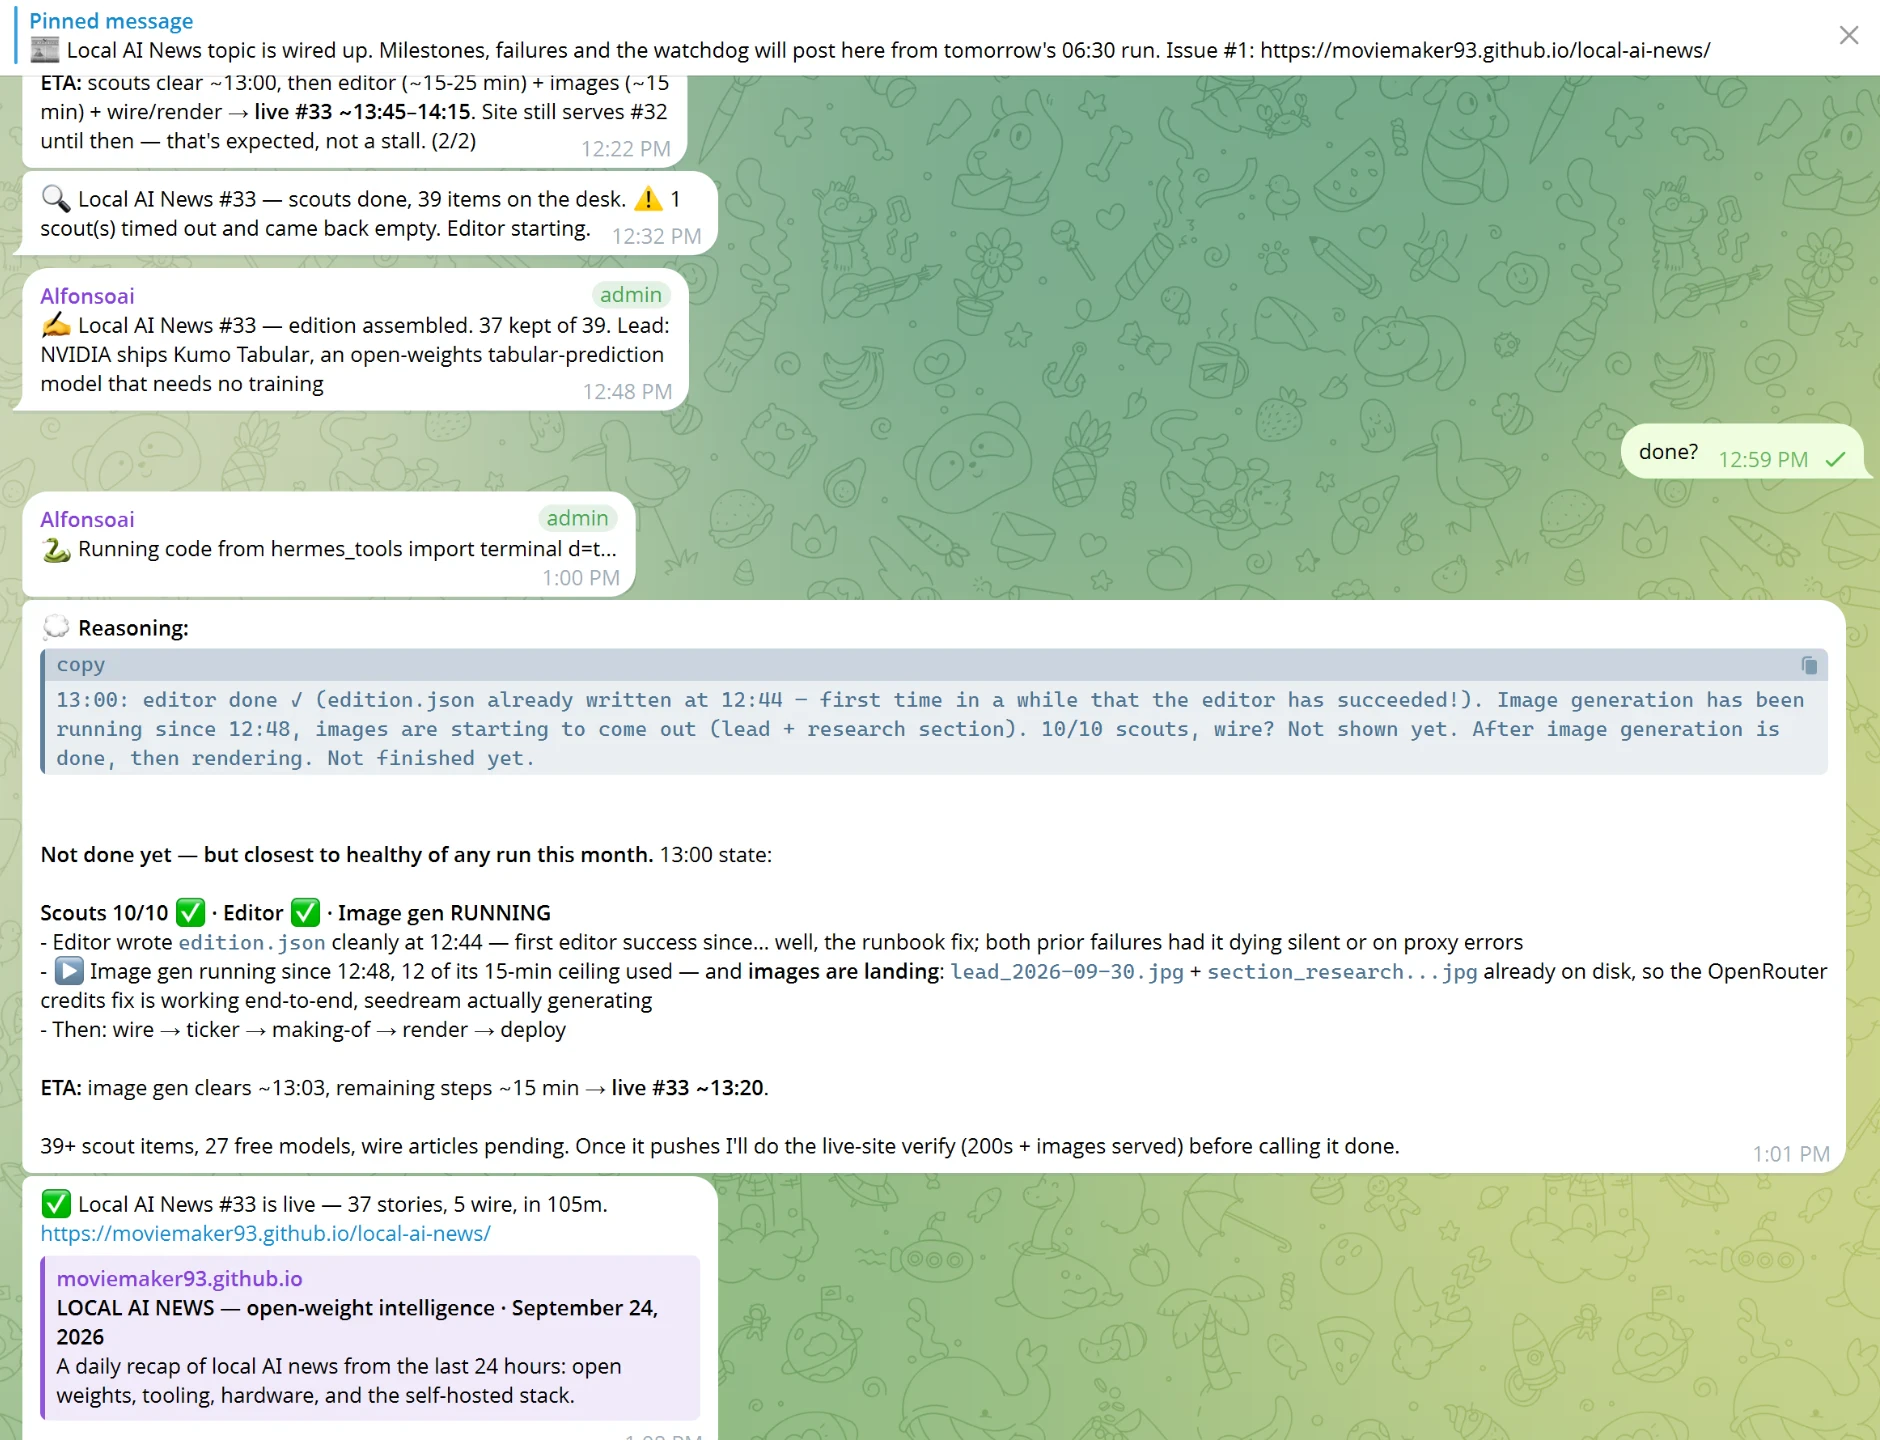
The architecture comes from NTTLuke's lux-in-tenebris-pipeline. I forked it and rebuilt it for local AI news.
The best approach: local AI plus one frontier model
For me, the best approach right now is to invest in local AI and keep a frontier model.
Last week Anthropic released Opus 5.5, and with its generous limits (they stretch about 25% further than with Opus 5) it's really the best option for having frontier capabilities on the hardest tasks. It also works great as the orchestrator/planner for your local model.
So this is what I'm going for right now:
- A $100 frontier model subscription (even $20 is enough): the hardest tasks, like kernel work to improve the inference engine and fine-tuning, plus orchestration and planning. (Not for creating new quantizations or abliterations, though. That's where the guardrails get in the way.)
- Local Qwen 3.8 Flash Next: coding tasks, cron-job routines on Hermes, searching online.
- Z.ai GLM Coding Plan ($40 per quarter): when I want multiple high-capability subagents, with GLM 5.3 Flash as the subagents and GLM 5.3 as the orchestrator.
In the future, if I buy another Spark, I can drop the Z.ai coding plan and downgrade my Claude/ChatGPT subscription.
What the future holds (and why Europe needs to wake up)
The future of AI is bright, but local AI hardware still has a big gap to close. Today only a small niche can afford a proper setup. The future I want is one where anyone can host a highly capable model at home.
The community is doing incredible work, but it can't close that gap alone. Hardware makers need to bring prices down, and governments need to start investing, especially in Europe. Right now Europe is disappointing. On August 31, the European Commission designated ChatGPT a "very large online search engine" under the Digital Services Act, in the same batch as Reddit and Roblox (European Commission). Europe regulates ChatGPT like a search box instead of treating it as the infrastructure it's becoming. At least France is waking up. At the UN General Assembly on September 22, Macron called on countries to pool their investments and build an open-source frontier model that doesn't depend on the US or China (France 24, AFP). That's exactly what we need: our own open models, running on our own hardware, free from the American/Chinese duopoly.
But you don't have to wait for Brussels or NVIDIA to get started. Pick the model that fits your GPU, grab a recipe from the accounts above, plug it into a harness, and try it this weekend. And if you can write a bit of Python or CUDA, contribute to an engine like TensorFold: every merged PR makes the same hardware faster for everyone.
OpenAI can halve your usage overnight. Nobody can do that to the model running on your desk.
AI is for everyone.
Follow me
If you liked this article, follow me on X at @devopsfortunato for more on local AI and the DGX Spark.
You can find my code on GitHub at MovieMaker93:
- My TensorFold contributions: faster prefill for Qwen 3.8 Flash Next on the DGX Spark, output bit-identical.
- dsh-plugin-safe-upgrade: safe upgrades and automatic rollback for DeepSeek Harness.
- dgx-spark-field-notes: experiments, deployments and benchmarks of AI models on the DGX Spark.
- Local AI News and its pipeline: a daily newspaper about local AI, written by agents running on my Spark.
References
Cloud AI prices
- Engadget: OpenAI adds $500(!) Pro subscription, nerfs its existing $200 tier
- The Next Web: OpenAI halves Pro 200 usage and launches a $500 ChatGPT plan at DevDay
- WinBuzzer: OpenAI adds $500 ChatGPT Pro plan, cuts allowance for new $200 plan subscribers
- PhoneArena: OpenAI to experience $14 billion losses by 2026
- Fortune: Sam Altman says OpenAI is losing money on ChatGPT Pro (January 2025)
- Axios: Don't get used to cheap AI
- Anthropic: Introducing Claude Opus 5.5
- Memeburn: Opus 5.5 costs 40% less to run, subscribers get about 25% more room
Guardrails, security and privacy
- Fortune: Hugging Face turns to Chinese open-source AI to fend off an autonomous AI cyberattack
- CNBC: How a Chinese AI model stopped OpenAI's "unprecedented" cyber attack
- Hugging Face: Be Ready Before the Attack: self-hosting an open model for cyber defense
- Anthropic: GLM-5.3 and the spread of advanced cyber capabilities
- Anthropic: Updates to Consumer Terms and Privacy Policy
Open models and hardware
- Epoch AI: Open-weight models
- Tom's Hardware: China's open-weight AI models are now just 4 months behind (Mozilla report)
- Tom's Hardware: NVIDIA DGX Spark gets a $700 price hike as memory shortages bite
- Windows Report: NVIDIA DGX Spark hits $5,000
- NVIDIA: DGX Spark / GB10 user forum
Quantization
- NVIDIA: Introducing NVFP4 for efficient and accurate low-precision inference
- ExLlamaV3 / EXL3 by turboderp
- DwarfStar (ds4) by antirez
- Unsloth: how to run Qwen 3.8 locally
- AutoRound by Intel
- AWQ by MIT Han Lab
Inference engines
- llama.cpp
- vLLM
- SGLang
- TensorFold by @ashxhart, and my PRs #40, #73 and #93
- llm_context_benchmarks by Ivan Fioravanti, the tool behind the TensorFold vs vLLM chart
Recipes
- Mia's AI Lab: GitHub and recipe catalog
- Mia's AI Lab: Qwen 3.8 Flash Next on one DGX Spark
- Mia's AI Lab: GLM 5.3 Flash EXL3 on 2–4 DGX Sparks
- Tech2Wild: X and GitHub
- Tech2Wild: GLM 5.3 Flash NVFP4 + DFlash2 on 2 DGX Sparks
- 0xSero: local-ai-registry
Harnesses and tools
- Pi (GitHub)
- OMP (Oh My Pi)
- OpenCode
- DeepSeek Harness, Tech2Wild's DeepSeek Harness tools, and Hikari's Smart-DSH
- ZCode, Z.ai's desktop harness for GLM-5.3
- MiniMax Code
- Hermes Agent
- herdr
- lux-in-tenebris-pipeline by NTTLuke, the original architecture behind Local AI News