
Available for collaboration
Measured local AI. Production-minded infrastructure.
I'm Alfonso. Local AI is my obsession: I benchmark local models on my own DGX Spark and publish field notes from building secure, cloud-native infrastructure.
Tools and technologies I work with: Local AI, DGX Spark, Kubernetes, GitOps, + 6 more
Latest writing
All articlesWhy I'm Betting on Local AI (and How You Can Start)
LLMLocal AIDGX Spark
OpenAI just halved its $200 plan and closed models keep adding guardrails. Why I'm betting on local AI, and how to start with quantization, inference engines, recipes and harnesses.
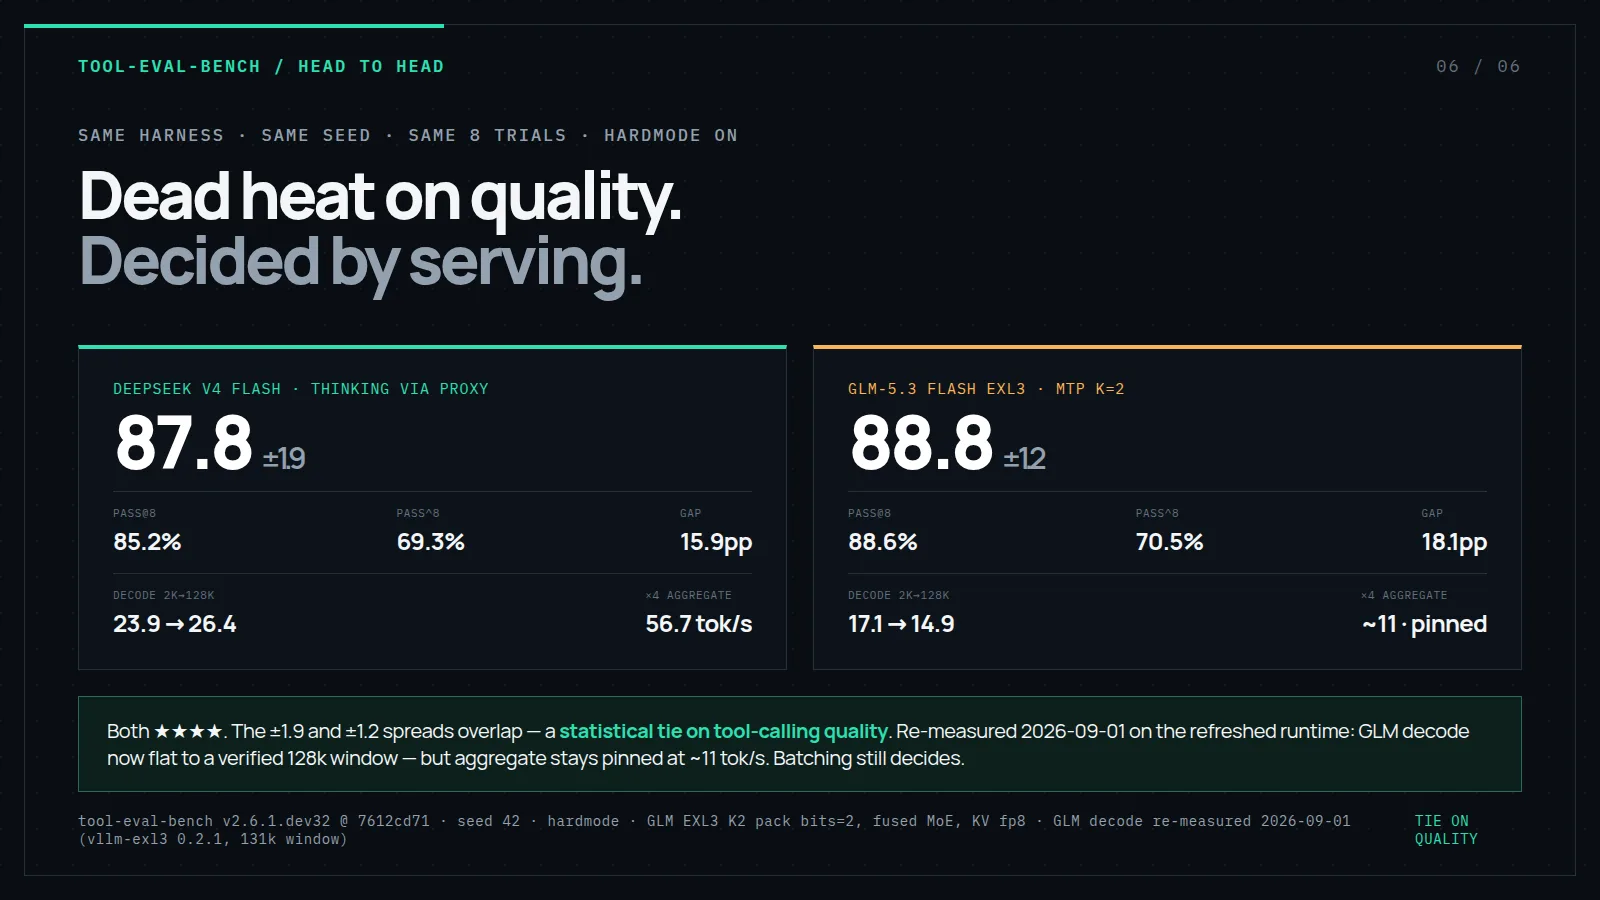
Measured on one DGX SparkTensorFold 53–90 tok/s vs vLLM 41–57 tok/s · 256k prompts 2.1× fasterReal-world speed, measured by me. No vendor marketing numbers.- DeepSeek V4 Flash vs GLM 5.3 Flash: Who Wins on a Single Spark?
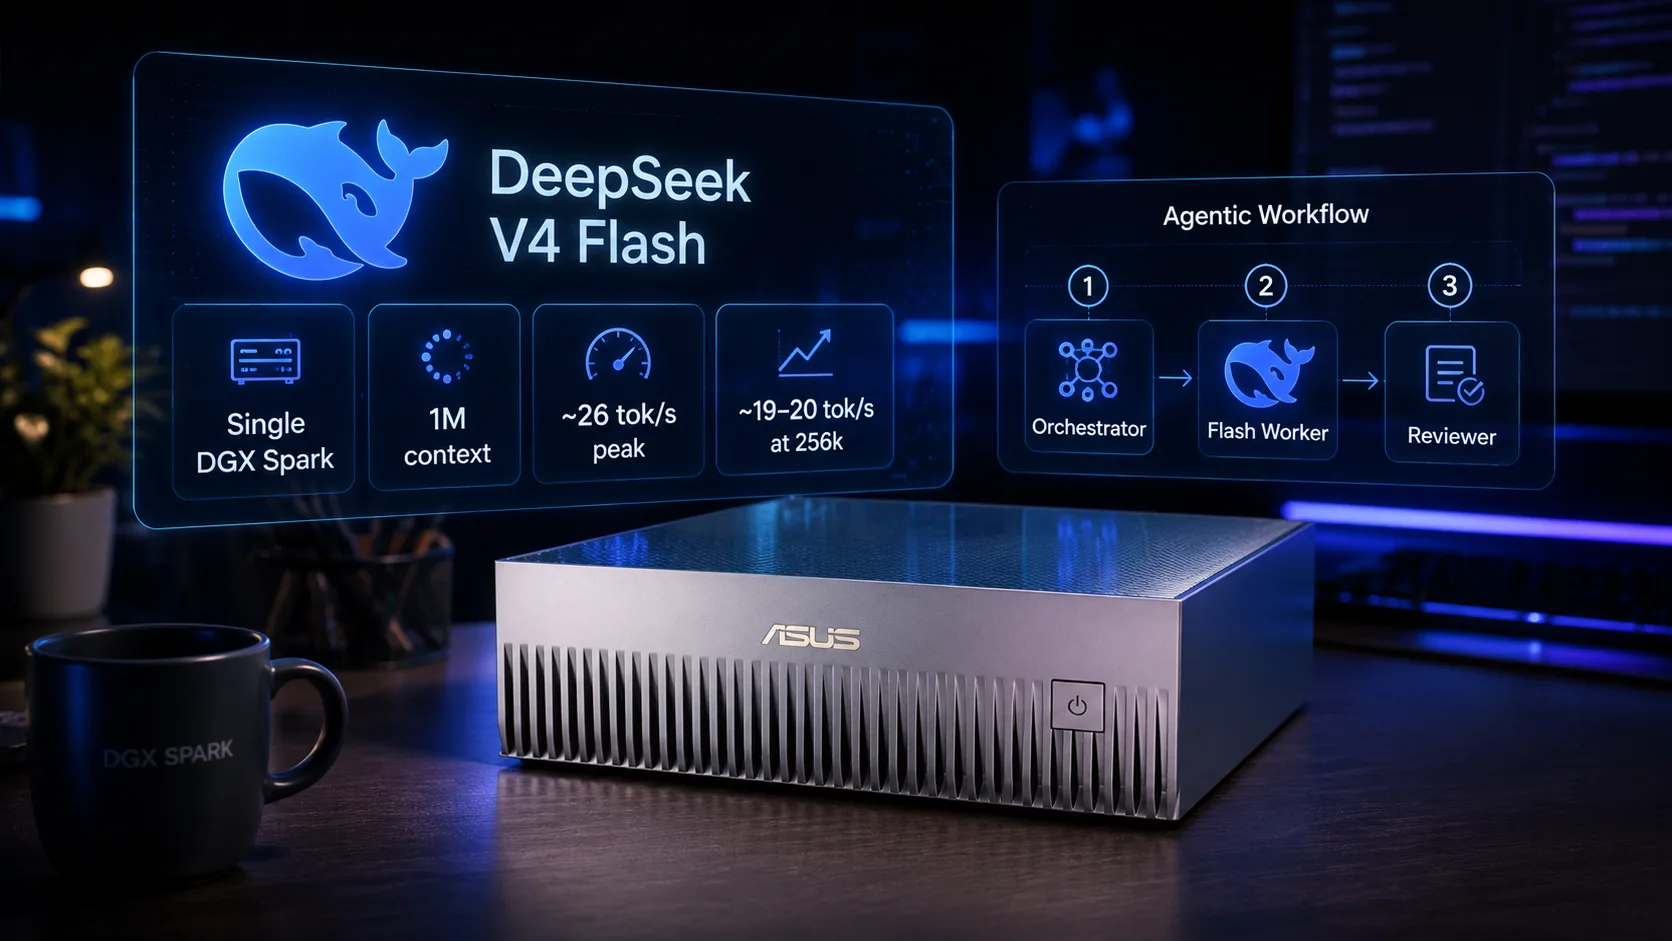
- DeepSeek V4 Flash on a Single DGX Spark
- Running Laguna S 2.1 on a DGX Spark
- My Obsidian PKM Setup: Karpathy's LLM Wiki + Claude Code + Local Search